Photo of Yunze Man

Yunze Man 「满运泽」

Research Scientist, NVIDIA GEAR · Robot Foundation Models

I build generalist robots across the full stack, from pre-training to deployment. At NVIDIA GEAR, I work on GR00T robot foundation models; on the data engine and reward models used to train them; on agentic orchestration for long-horizon tasks; and on the infrastructure that runs these models on real robots and measures what works.

I received my Ph.D. in Computer Science from UIUC, advised by Yuxiong Wang and Liangyan Gui and supported by the NVIDIA Graduate Fellowship, and my M.S. in Robotics from CMU, advised by Kris Kitani.

Email: 
[Google Scholar] [GitHub] [LinkedIn] [X]

News

  • [10/2026]    Open-sourced Flora, the data engine used to train GR00T models: open models that caption robot and human video and judge task success and action quality.
  • [06/2026]    Released Vesta, a generalist embodied reasoning model that plans, remembers, and delegates execution to GR00T policies.
  • [06/2026]    Defended my PhD thesis “Visually Grounded Multimodal Models for Spatial Intelligence”!
  • [05/2026]    Joined NVIDIA GEAR full-time as a Research Scientist, working on GR00T robot foundation models.
  • [03/2026]    Gave a Lightning Talk on LocateAnything3D at NVIDIA GTC 2026.
  • [02/2026]    LocateAnything3D and Fast-ThinkAct accepted to CVPR 2026; Capturing accepted to ICLR 2026.
  • [12/2025]    Released GR00T N1.6, an open robot foundation model for humanoid and bimanual robots.
  • [12/2025]    Launched Lux, OpenAGI's computer-use agent, and open-sourced OSGym for training computer-use agents.
Show more ▾

What I Work On

Robot foundation models

Generalist policies that turn vision and language into action. I work across the full training pipeline of GR00T models: pre-training for broad capability, mid-training for new skills, and post-training for reliability on real robots.

Data engine & reward models

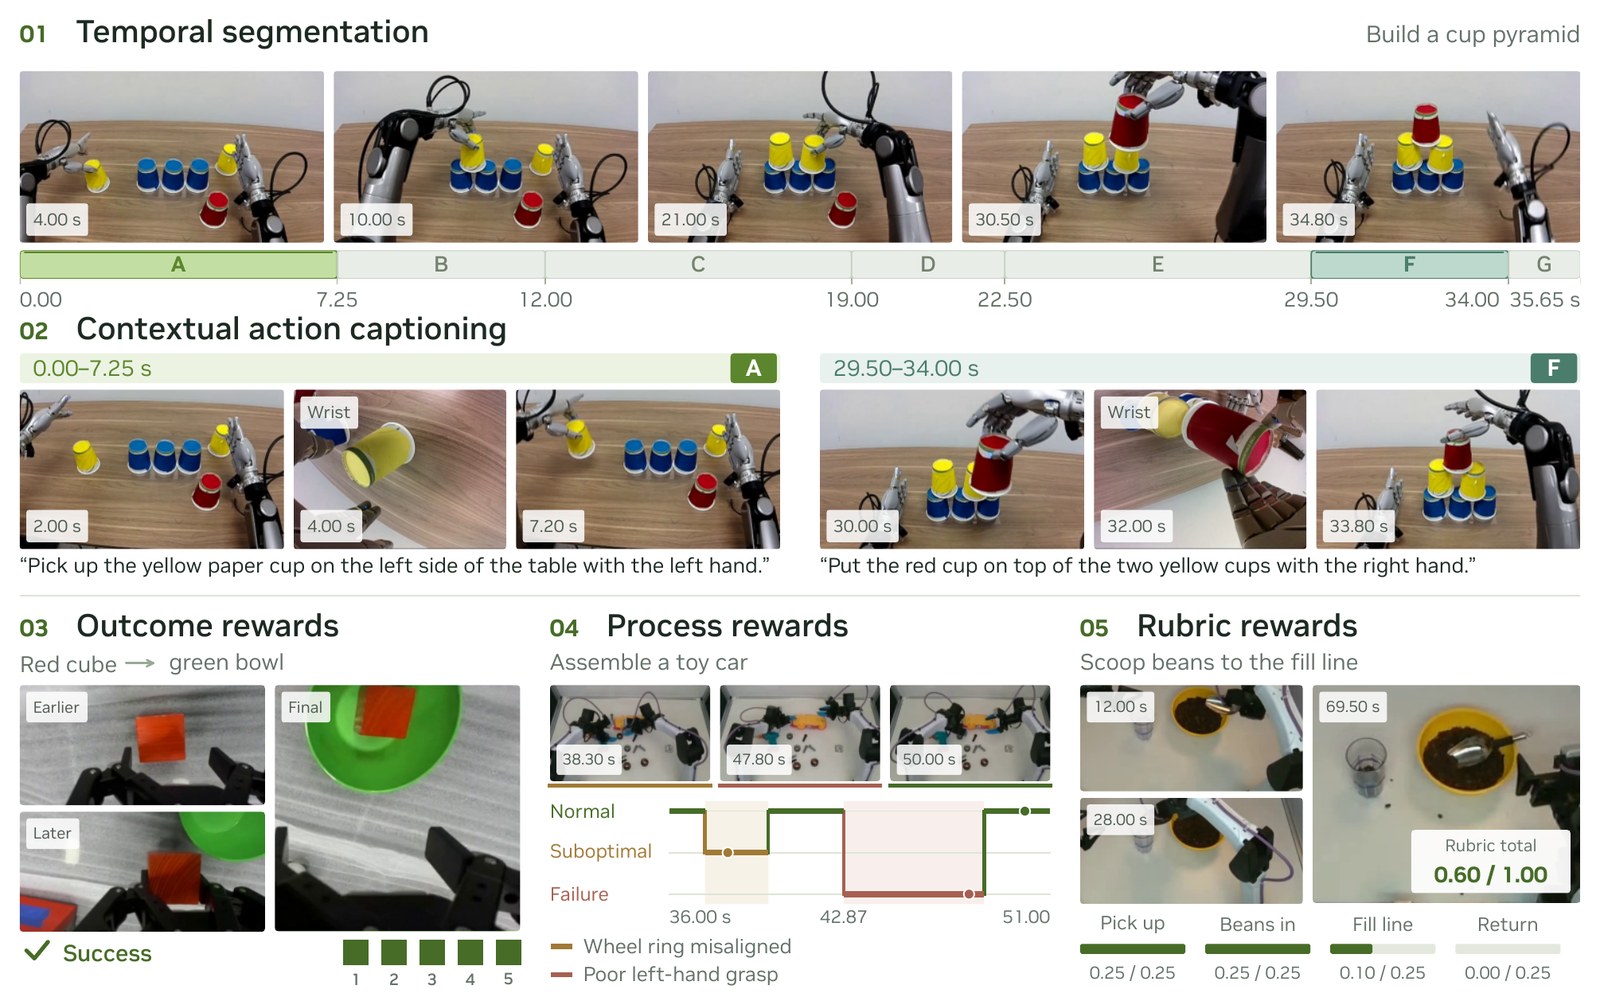
VLMs that turn raw robot and human video into training signal: what happened, when each step ends, and whether it worked. At scale, this becomes the robot's data engine: Flora labels 200,000 hours of video per day. Used as a critic, it becomes the reward model for monitoring deployments and RL post-training.

Agentic orchestration & Sim2Real

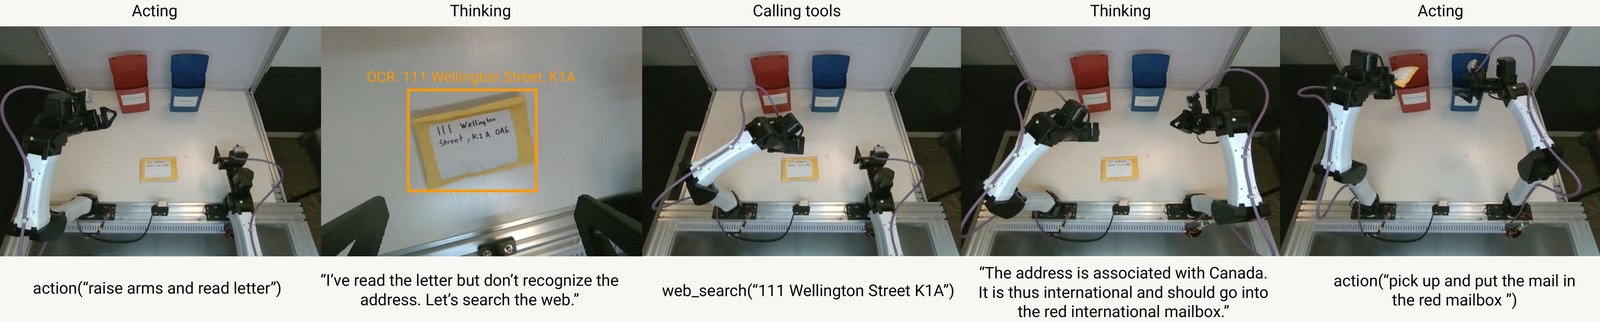
Developing VLM orchestrators to guide the robot: deciding what to do next, tracking progress, and delegating execution to the policy. Plan, remember, and recover. Training in simulation lets us scale compute instead of robot hours, and Sim2Real carries the result to real robots.

Real-robot deployment & evaluation

Making real-robot execution fast and smooth, and building evaluation that tells us what actually works: fair comparisons on the robot, and offline signals that guide iteration between robot runs.

What we want from a real robot is simple: finish the task, every time, with smooth and safe motion. No single layer gets us there: it takes pre-training, post-training, infrastructure, and deployment working together.

Selected Publications

Please refer to my Google Scholar profile for the full list of publications.

(* indicates equal contribution)

Robot Foundation Models, Embodied Reasoning & Agents

Flora
Flora: An Open Model Suite for Scaling Robotics Data Engines
Sicong Leng*, Yunze Man*, Zhiqi Li*, Jing Wang, Yuhe Zhang, Ryan Punamiya, Siddharth Patki, Kaiyuan Zheng, Zi-ang Cao, Zhiding Yu, Sifei Liu, Danfei Xu, Ben Levin, Jan Kautz, Yuke Zhu, Johan Bjorck*, Linxi “Jim” Fan
Tech Report 2026 / Paper / Project / Code / Models
The open data engine used to train GR00T models: timestamped captions and reward labels for robot and human video.
Vesta
Vesta: A Generalist Embodied Reasoning Model
Johan Bjorck*, Zhiqi Li*, Yunze Man*, Jing Wang*, An-Chieh Cheng, Sifei Liu, Shihao Wang, Zhiding Yu, et al.
Tech Report 2026 / Paper / Project
An embodied reasoning model that plans, remembers, and delegates to GR00T policies.
GR00T N1.6
GR00T N1.6: An Improved Open Foundation Model for Generalist Humanoid Robots
NVIDIA GEAR Team
Tech Report 2025 / Project / Code / Model Card
Open vision-language-action foundation model for humanoid and bimanual robots.
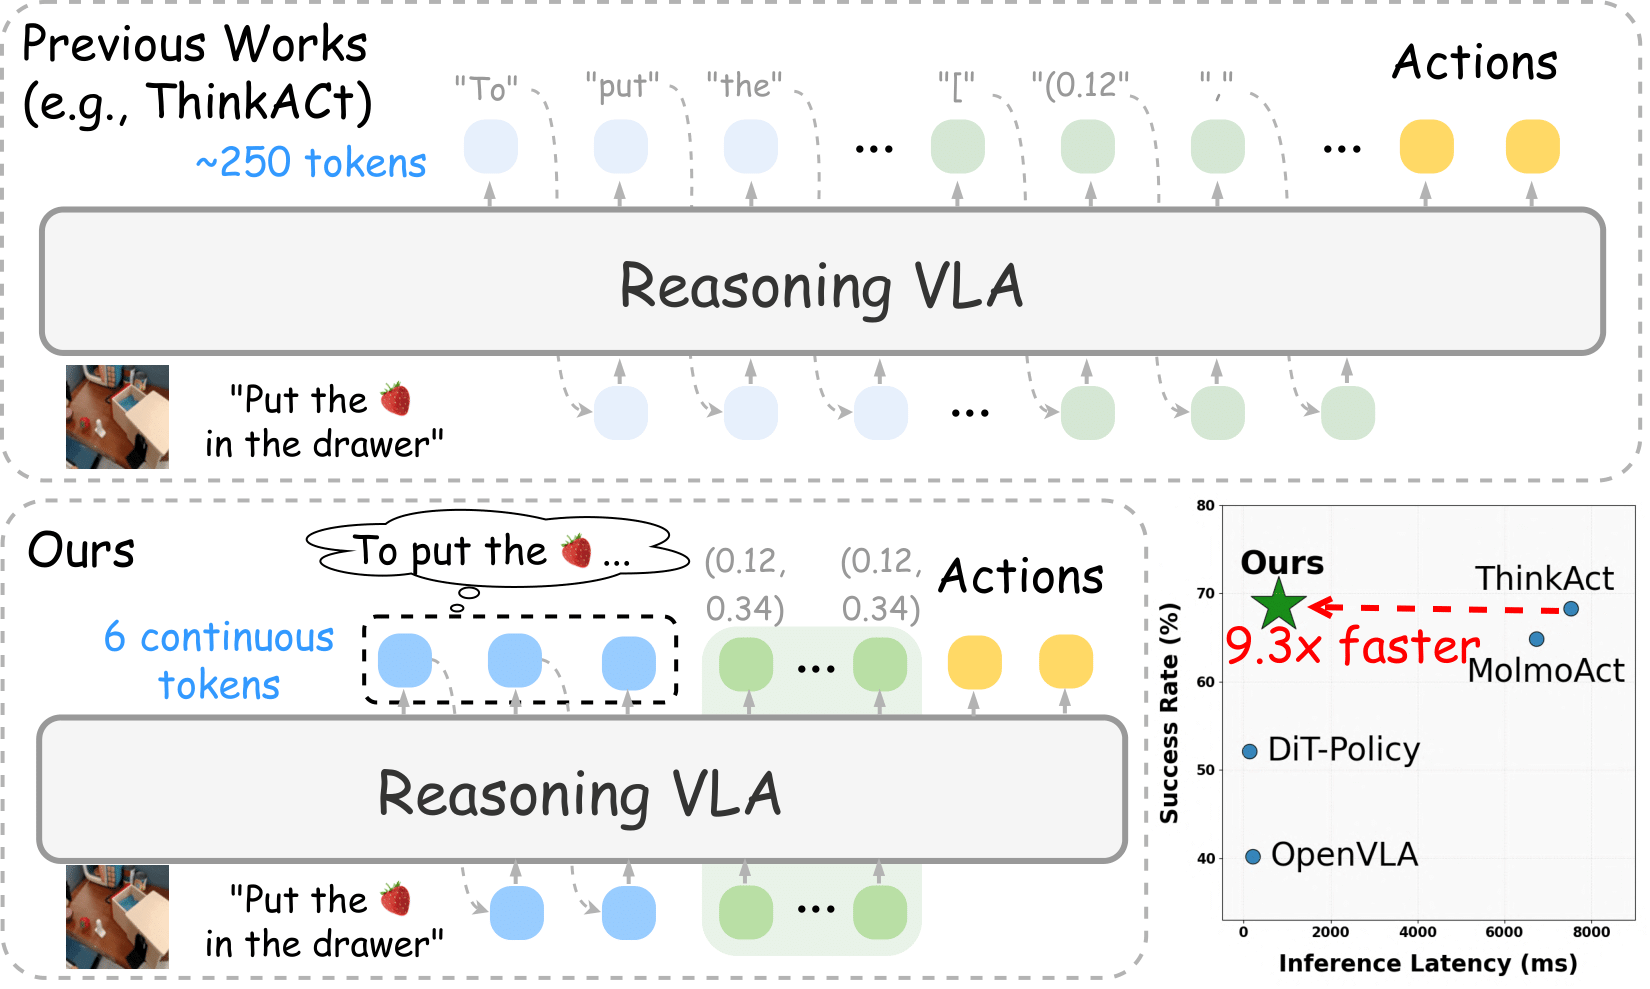
Fast-ThinkAct
Fast-ThinkAct: Efficient Vision-Language-Action Reasoning via Verbalizable Latent Planning
VLA reasoning with compact latent plans instead of long chains of thought.
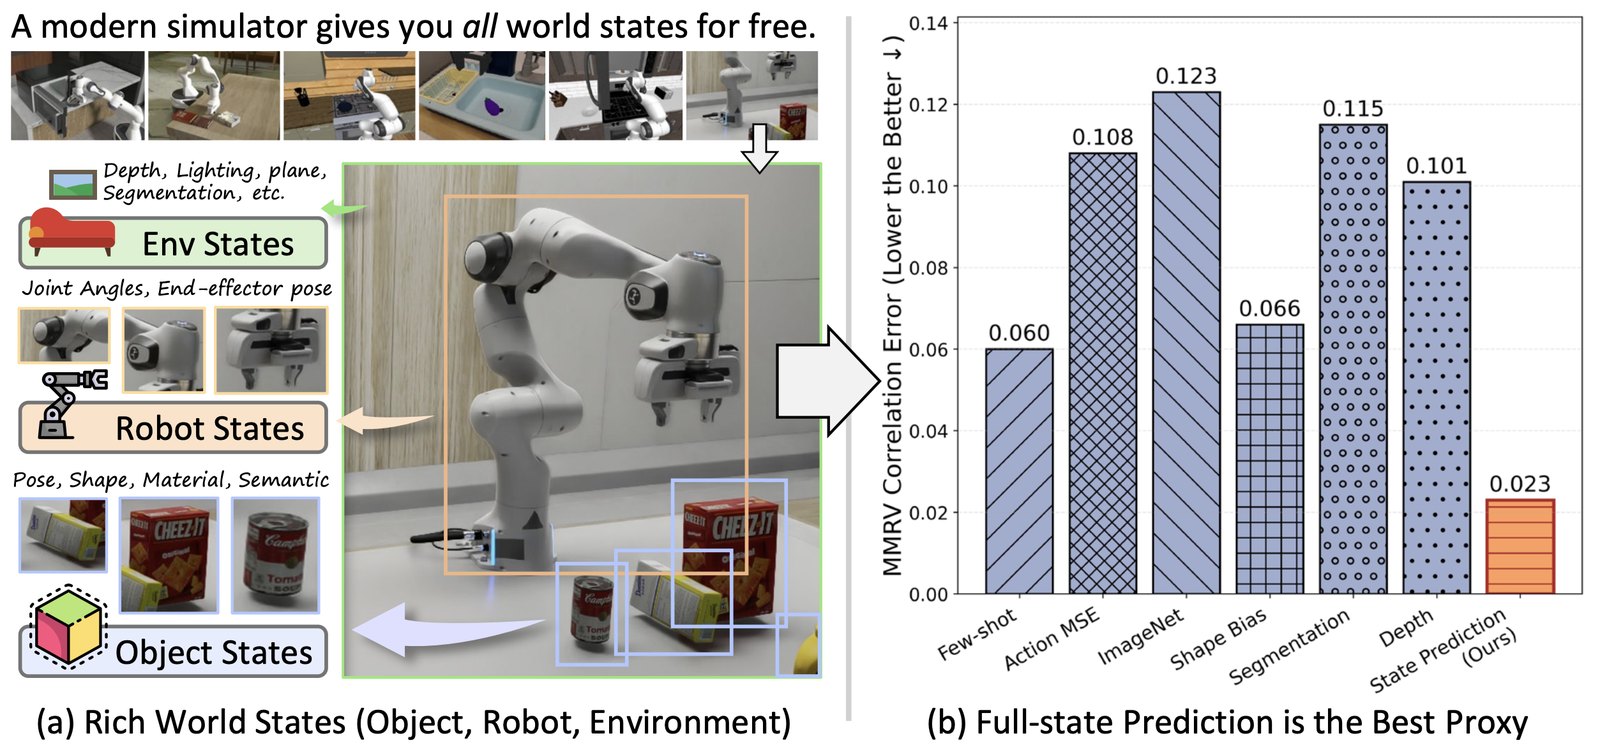
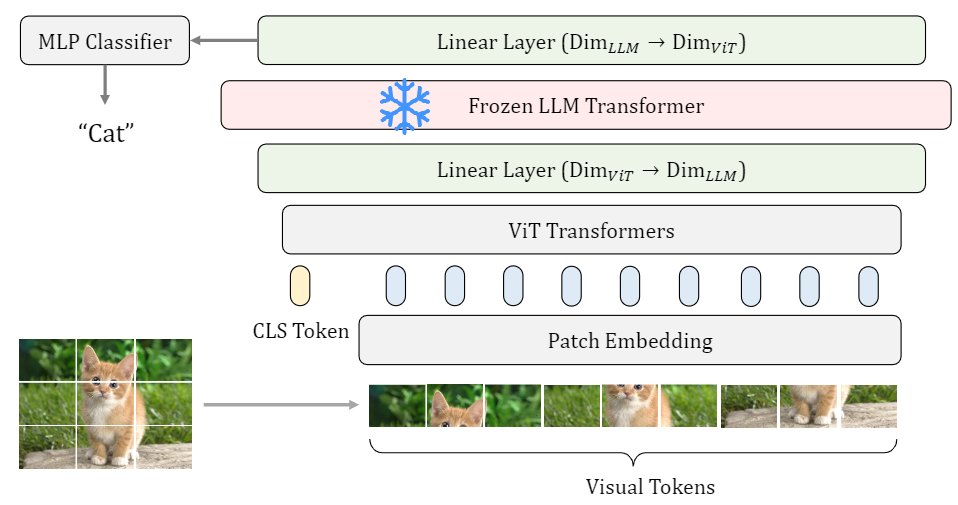
Capturing
Capturing Visual Environment Structure Correlates with Control Performance
How well a visual representation captures world state predicts how well it controls.
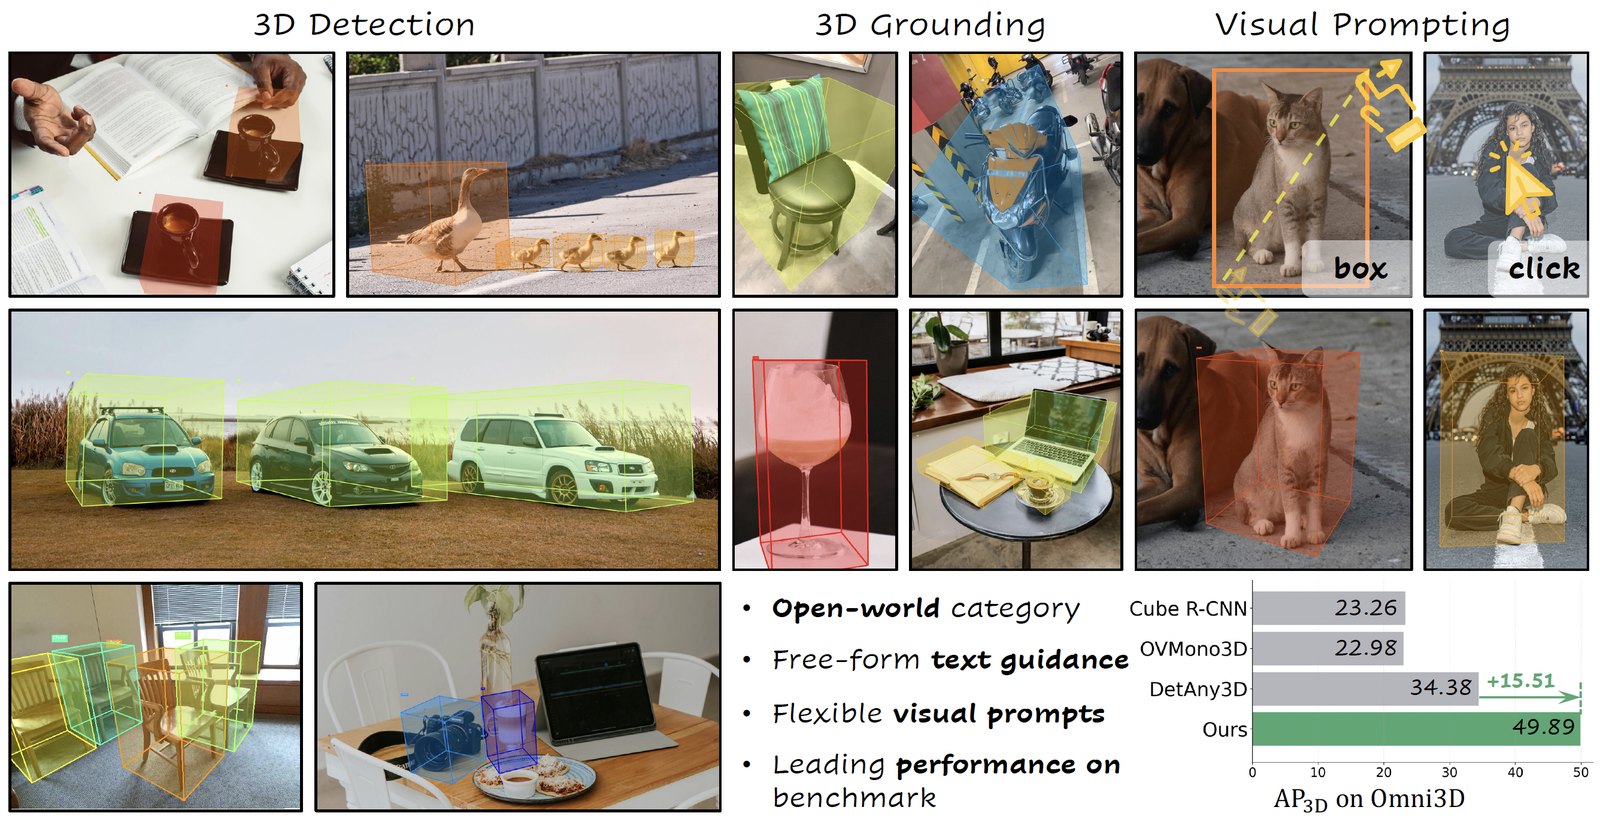
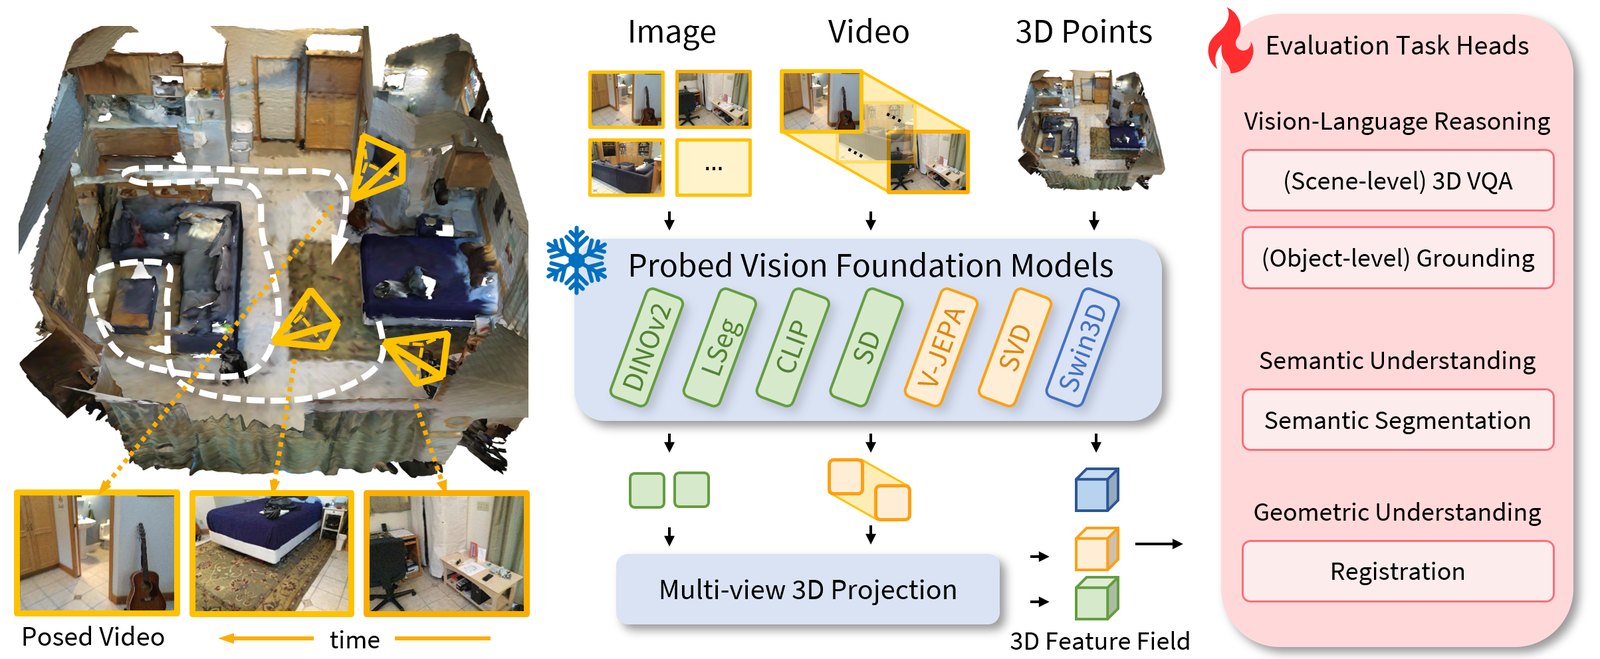
LocateAnything3D
LocateAnything3D: Vision-Language 3D Detection with Chain-of-Sight
Open-vocabulary 3D grounding, native to VLMs.
LocateAnything
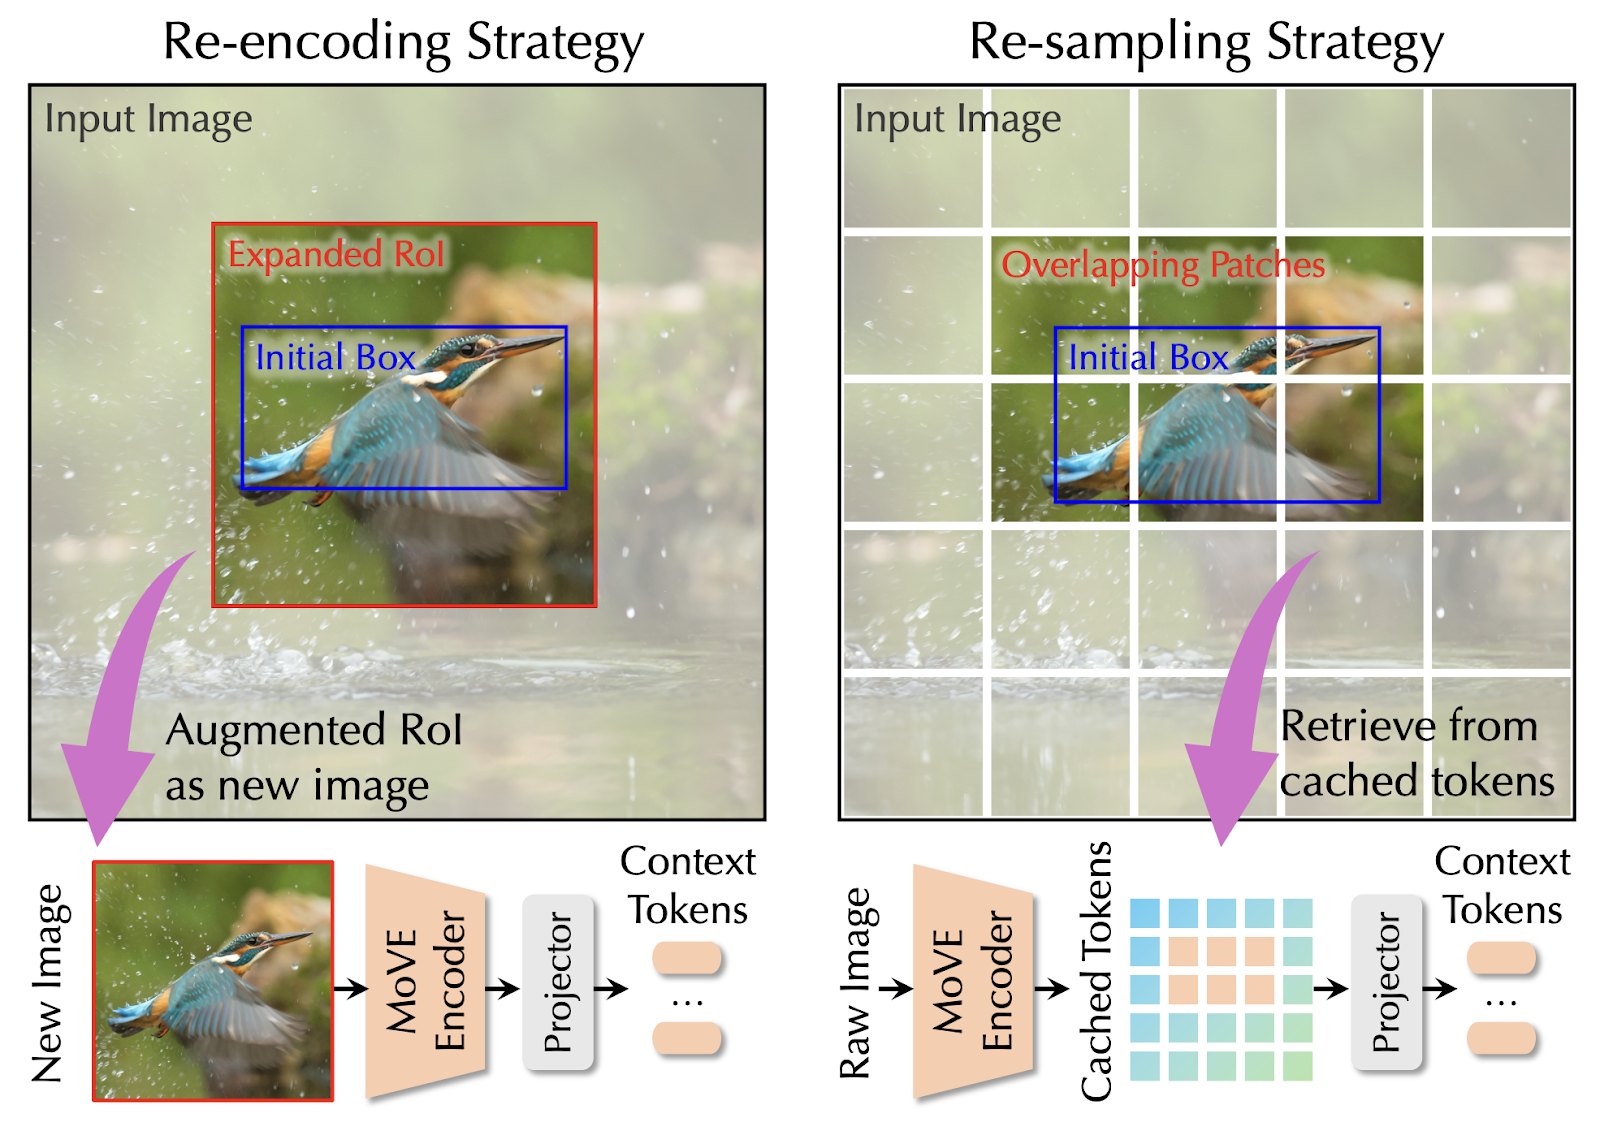
LocateAnything: Fast and High-Quality Vision-Language Grounding with Parallel Box Decoding
Shihao Wang, Shilong Liu, Yuanguo Kuang, Xinyu Wei, Yangzhou Liu, Zhiqi Li, Yunze Man, Guo Chen, Andrew Tao, Guilin Liu, Jan Kautz, Lei Zhang, Zhiding Yu
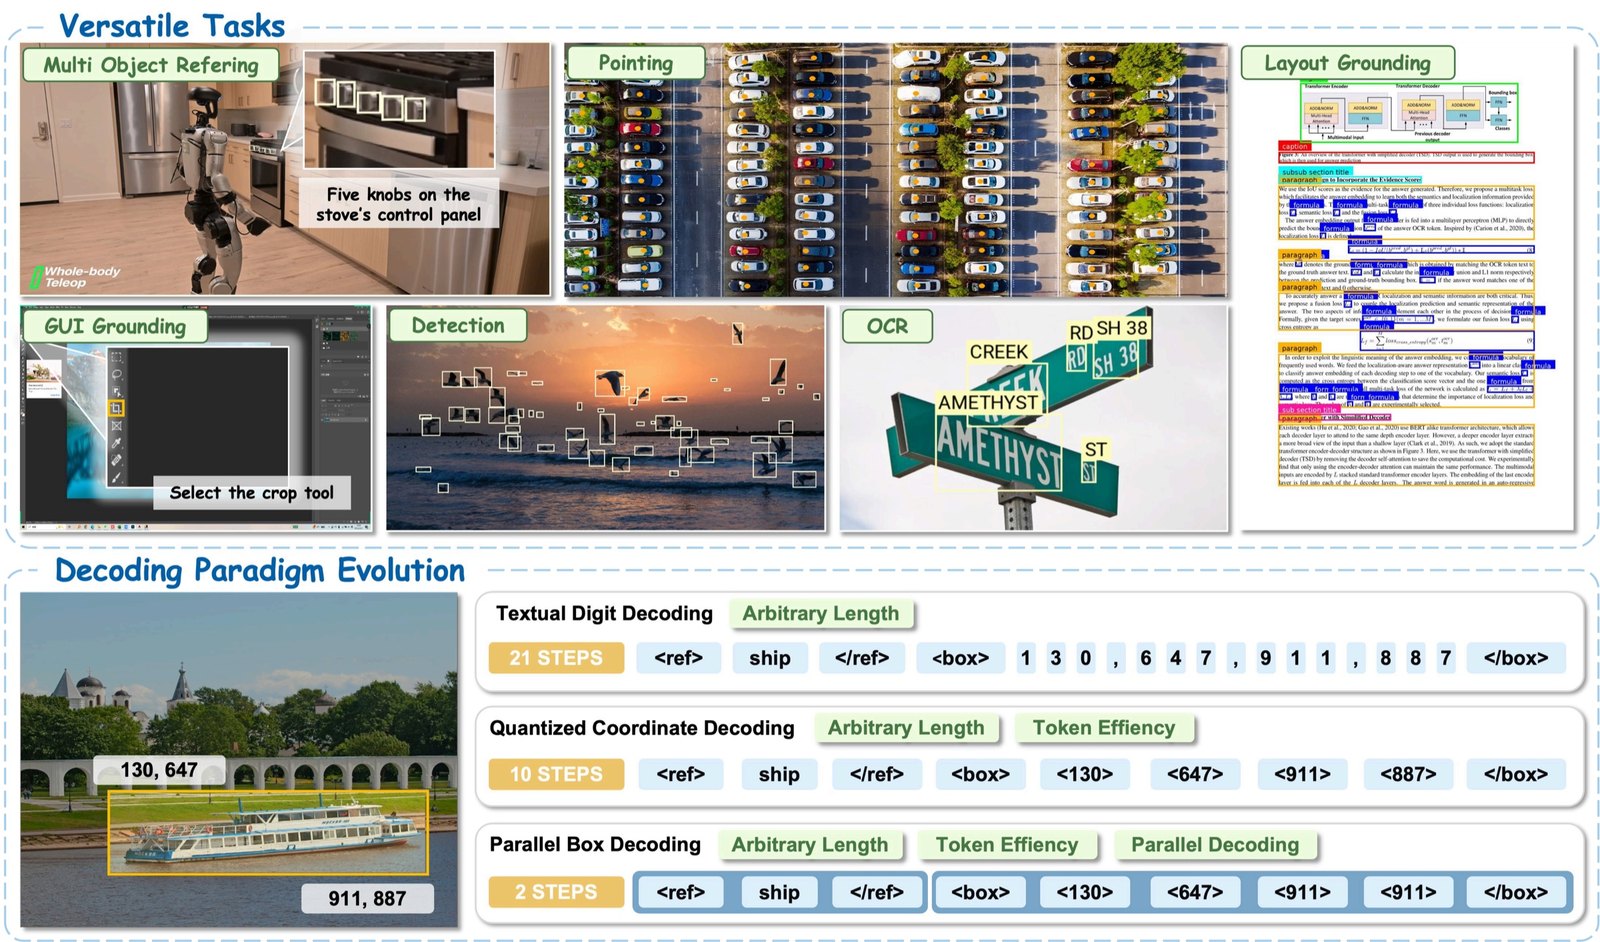
Fast, accurate VLM grounding by decoding boxes in parallel.
Argus
Argus: Vision-Centric Reasoning with Grounded Chain-of-Thought
VLM reasoning grounded in explicitly localized visual evidence.
OSGym
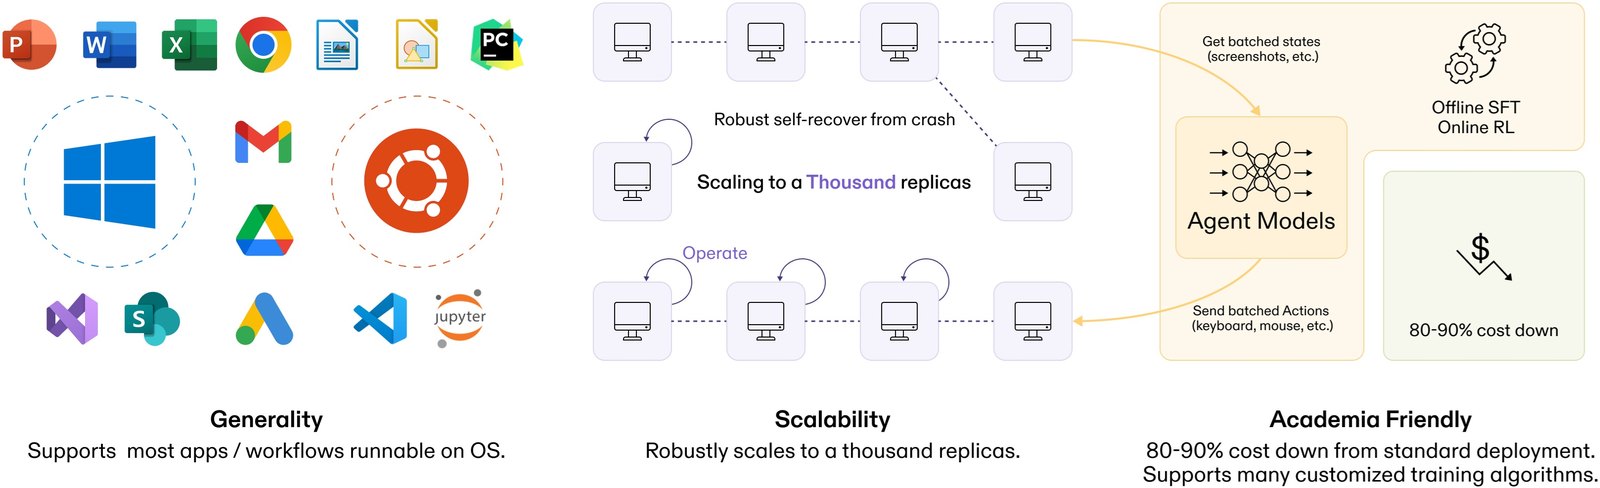
OSGym: Super-Scalable Distributed Data Engine for Generalizable Computer Agents
Zengyi Qin, Jinyuan Chen, Yunze Man, Shengcao Cao, Ziqi Pang, et al., Jitendra Malik, Pieter Abbeel
Tech Report 2025 / Paper
Scalable infrastructure that runs full operating systems to train computer-use agents.

Earlier Work: 3D Perception, Spatial Reasoning & Generative Models

Show earlier work ▾

Experience

  • NVIDIA GEAR (Generalist Embodied Agent Research), Research Scientist 05/2026 – Present
    GR00T robot foundation models; data engine and reward models (Flora); agentic orchestration (Vesta); real-robot deployment and evaluation.
    Research intern 08/2025 – 03/2026.
  • OpenAGI Foundation, Founding Researcher 12/2024 – 03/2026
    Lux, a computer-use agent; OSGym, scalable infrastructure for training computer-use agents.
  • NVIDIA Learning and Perception Research, Research Scientist Intern 05/2024 – 12/2024
    Grounded visual reasoning for VLMs.
  • Adobe Research, Research Scientist Intern 05/2022 – 08/2022
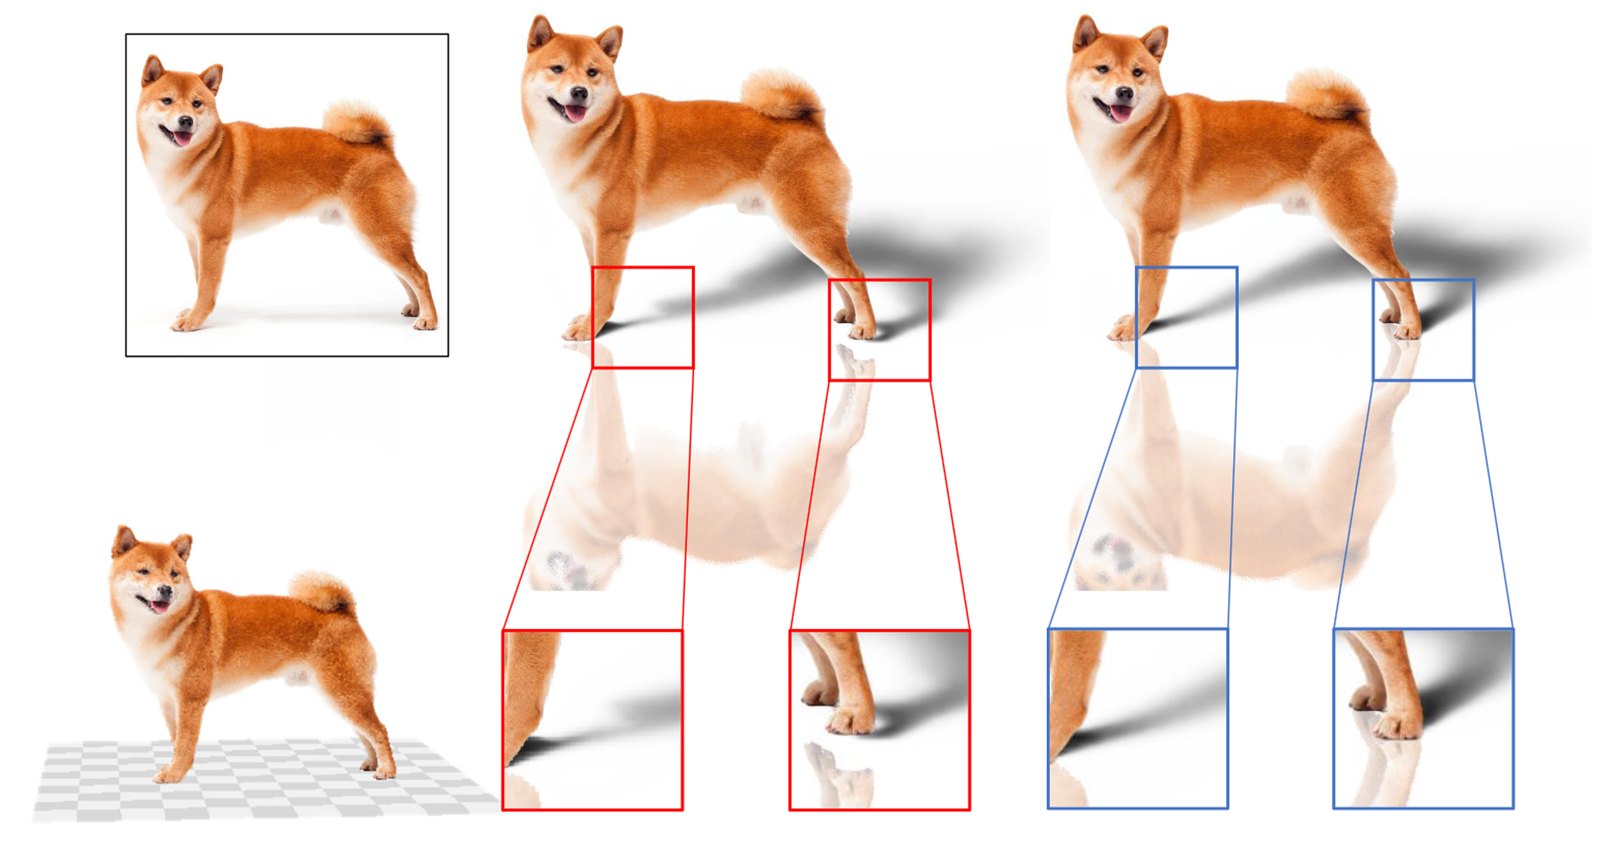
    Single-image 3D object-ground reconstruction.

Education

  • University of Illinois Urbana-Champaign, Ph.D. in Computer Science 2021 – 2026
    Advisors: Yuxiong Wang and Liangyan Gui. Thesis: Visually Grounded Multimodal Models for Spatial Intelligence.
  • Carnegie Mellon University, M.S. in Robotics 2019 – 2021
    Advisor: Kris Kitani.
  • Zhejiang University, B.Eng. in Computer Science 2015 – 2019

Honors & Service

  • NVIDIA Graduate Fellowship, one of 10 recipients worldwide 2025
  • Top Reviewer, NeurIPS 2024; Outstanding Reviewer, CVPR 2024 2024
  • Reviewer for ICRA, IROS, NeurIPS, ICLR, ICML, CVPR, ICCV, ECCV, AAAI, TMLR, WACV 2021 – 2026
  • Teaching Assistant: Machine Learning and two graduate seminars at UIUC; Computer Vision Capstone at CMU 2020 – 2022